
Physical RSI:
Learning to Improve,
in the Physical World
Helping robots learn new skills faster—and master increasingly complex skills.
Turning every real-world deployment into a shorter adaptation cycle for the next manufacturing operation.
In this article · 7 sections
Why Physical RSI, when we already have RL?
Robots still face a gap between being able to perform a task and performing it reliably over time. Pretraining and imitation learning provide a starting point, but changes in contact conditions, variations in objects, and failure recovery in real deployments require further experience and adaptation. Within clearly defined skill domains, we aim to keep improving success rates, speed, and robustness, while exploring performance beyond human capabilities.
For industrial customers, a key value of intelligence is flexibility:
How long does it take to adapt to a new manufacturing operation?
A policy that has learned to insert and remove a connector will not necessarily meet requirements quickly when the connector, fixture, or process changes. RL enables skills to improve through trial and error, but an entire system determines how success is judged, how the environment is reset, where practice takes place, and what changes after a failure. When people maintain most of these conditions, it is hard to keep shortening the adaptation cycle for each new capability. R&D efficiency is a means to an end; customers care about the time between a new requirement and reliable deployment.
The goal of Physical RSI is to learn new skills faster and master increasingly complex skills. Deployment experience should improve not only actions, but also evaluation, training environments, and experimental workflows. Solving a problem today can then help the system overcome a harder challenge tomorrow.
Physical RSI builds on ideas from RL, continual learning, and meta-learning. RL itself can learn curricula, rewards, or meta-policies; the distinction here lies in the scope of improvement and how it is validated. We use Physical RSI to describe how an entire system is organized for recursive improvement, rather than a new optimization algorithm that replaces RL.
Improving the learning system—and the physical body
Self-improvement makes a system more capable; recursive self-improvement makes it better at improving itself in the next round. Collecting another batch of data or periodically retraining a model does not, by itself, demonstrate recursive improvement. We must also establish whether the method for acquiring new capabilities has become more effective.
We explore two parallel paths that can reinforce each other. Algorithmic RSI focuses on the learning system: automatically identifying problems, forming hypotheses, designing and validating experiments, and carrying effective methods into the next round. It improves policies, evaluators, environments, data selection, and training workflows.Embodiment RSI focuses on the robot's physical body: identifying physical limitations through real failures, connecting design, fabrication, replacement, calibration, and policy adaptation, and ultimately improving the tools and methods used to design and build the body itself.
The two paths correspond to the work of Auto Research and Auto Engineering, respectively. The relationship becomes recursive only when their results further improve the system's own capacity to improve. Better learning systems help identify physical bottlenecks; better bodies enable more reliable manipulation, richer observations, and more efficient experiments.
This article focuses on Algorithmic RSI. We will develop Embodiment RSI in subsequent work, using the super workstation jointly proposed with Yuantu as a platform for iterating on robot embodiment.
Two independent capability scales
The following is our proposed framework, not an industry standard. AL0–AL3 describe the ability to improve a learning system, while EL0–EL3 describe the scope of physical engineering that can be improved. They are assessed independently; placing them side by side does not imply a one-to-one correspondence.
| Algorithmic | Objective | Capability boundary | Embodiment | Objective | Capability boundary |
|---|---|---|---|---|---|
| AL0 | Human-led learning system iteration | People design evaluation, curricula, and training workflows, and decide how to improve them. Models learn skills within the prescribed workflow. | EL0 | Human-led embodiment iteration | People identify physical limitations, propose designs, and organize fabrication and testing. The system supplies data or performs tests. |
| AL1 | Skill optimization within a fixed learning framework | Within human-defined tasks, rewards, and training environments, the system automatically collects interactions, updates policies, and evaluates results to improve success rates, cycle times, and recovery. People still lead the design and improvement of the learning system. | EL1 | Autonomous discovery of physical limitations | The system identifies physical bottlenecks through task failures and physical tests, and designs validation experiments to distinguish policy, calibration, and hardware issues. People still lead physical modifications and implementation. |
| AL2 | Coordinated iteration that improves learning efficiency across tasks | Deployment failures drive coordinated updates to policies, evaluators, and training environments. Diagnosis, intervention, and validation produce reusable learning methods. Multiple rounds must show that new tasks meet requirements faster under comparable budgets. | EL2 | An autonomous embodiment improvement loop | The system diagnoses problems and proposes design changes, then uses existing tools for fabrication, assembly, calibration, policy adaptation, and physical validation. The design, fabrication, and testing tools themselves remain largely fixed. |
| AL3 | Expanding the limits of learning methods and task complexity | The system proposes and validates new learning methods, evaluation mechanisms, or environment generation methods, learning increasingly complex tasks while continuing to improve learning efficiency. | EL3 | Recursive improvement of design and fabrication systems | The system identifies how design, fabrication, or testing tools constrain physical progress, and improves those tools and methods. It then uses the upgraded tools to build and validate a better body, making the next round of embodiment iteration more capable. |
Algorithmic RSI
Human-led learning system iteration
People design evaluation, curricula, and training workflows, and decide how to improve them. Models learn skills within the prescribed workflow.
Skill optimization within a fixed learning framework
Within human-defined tasks, rewards, and training environments, the system automatically collects interactions, updates policies, and evaluates results to improve success rates, cycle times, and recovery. People still lead the design and improvement of the learning system.
Coordinated iteration that improves learning efficiency across tasks
Deployment failures drive coordinated updates to policies, evaluators, and training environments. Diagnosis, intervention, and validation produce reusable learning methods. Multiple rounds must show that new tasks meet requirements faster under comparable budgets.
Expanding the limits of learning methods and task complexity
The system proposes and validates new learning methods, evaluation mechanisms, or environment generation methods, learning increasingly complex tasks while continuing to improve learning efficiency.
Embodiment RSI
Human-led embodiment iteration
People identify physical limitations, propose designs, and organize fabrication and testing. The system supplies data or performs tests.
Autonomous discovery of physical limitations
The system identifies physical bottlenecks through task failures and physical tests, and designs validation experiments to distinguish policy, calibration, and hardware issues. People still lead physical modifications and implementation.
An autonomous embodiment improvement loop
The system diagnoses problems and proposes design changes, then uses existing tools for fabrication, assembly, calibration, policy adaptation, and physical validation. The design, fabrication, and testing tools themselves remain largely fixed.
Recursive improvement of design and fabrication systems
The system identifies how design, fabrication, or testing tools constrain physical progress, and improves those tools and methods. It then uses the upgraded tools to build and validate a better body, making the next round of embodiment iteration more capable.
Learning skills—and improving how they are learned
Algorithmic RSI advances through two nested loops. Skill Learning Loop handles data collection and selection, supervised learning, reinforcement learning, and evaluation for a given skill, turning demonstrations and trial-and-error experience into execution capability. Training methods depend on the task; the loop is not limited to RL.
Deployment Loop uses problems exposed in real deployments to update evaluators, training environments, and experimental workflows. It then tests whether these changes make the next round of skill learning faster, more effective, and applicable to new manufacturing operations.
We use asynchronous RL combining simulated environments with a small number of real-robot environments. Both types collect interaction experience asynchronously for policy learning and evaluation. RimGround generates and edits simulated environments, emphasizing diverse noise and perturbations and efficient simulation. The real-robot environments supply physical feedback to test and calibrate the physical laws and parameters on which the components rely, keeping the learning system aligned with the real world.
Three components support this system: RimPilot answers “How do we accomplish the task?”, RimCritic answers “How well are we doing, and are we approaching failure?”, and RimGround answers “Where and what should we practice next?” RimCritic refers to the reward and evaluation model, not the value critic in an actor–critic algorithm.
Physical RSI requires models and the harness around them to evolve together. We will continue developing foundation models and improving policy and evaluation capabilities. In the near term, more of our time and resources will focus on skill learning and the overall improvement loop. The algorithmic harness includes data pipelines, training tools, experiment orchestration, and evaluation and validation mechanisms. A key element is automatic generation and editing of training environments: turning real weaknesses into reproducible training conditions, then testing the benefits on real robots.
In specific settings, we have already implemented the skill learning and adaptation loop corresponding to AL1. The super workstation jointly developed by RIMBOT and Yuantu has demonstrated adaptation to a new environment in under an hour. According to QbitAI's on-site WAIC report, the equipment was powered on at 4:30 p.m. in an environment with different lighting and spatial layout, and completed adaptation at 5:00 p.m. after about half an hour of training. The report also describes how a world reward model supplies task feedback, while a world policy model outputs actions and incorporates real execution experience.(QbitAI report, republished by the BAAI community ↗)
Under our framework, this provides a concrete example of AL1: updating a policy through interaction feedback and adapting within an established learning framework. Our current focus is to build on this foundation and advance toward AL2: improving environments and evaluators alongside the policy, then testing over multiple rounds whether new tasks meet requirements faster under comparable budgets.
Finding data diversity within a single task
In a structured industrial workstation, tasks, objects, layouts, and normal operating procedures are usually constrained. Routine behavior and environmental variation therefore offer relatively limited diversity. One lesson we have learned is that making full use of these settings requires not only collecting successful demonstrations, but actively exploring failure data. Even within a single task, failures can take many forms.
Consider connector insertion: the same intended motion can jam because of pose error, cause damage through excessive contact force, lose alignment through slipping, or appear complete without establishing electrical continuity. These illustrative cases expose different limits in perception, control, evaluation, or embodiment. For a system that outputs actions and continuously changes the physical world, identifying failure modes and the conditions that produce them is an essential part of understanding its own capabilities.
More broadly, we focus on boundary data. This includes failures near a capability boundary, narrow successes, early signs of failure, and successful recoveries. How much misalignment causes jamming? Which states remain recoverable after abnormal contact? Differences near the transition between success and failure often offer more diagnostic value than repeatedly recording failures far beyond the system's capabilities.
Autonomous driving evaluation offers related evidence. A roundabout study constructed a test space through diverse interactive behavior, adaptively generated challenging cases, and covered the system's failure modes more effectively in simulation.[5] Another study generated cases at different challenge levels for cut-in and unprotected left-turn scenarios, applying repeatable testing and quantitative evaluation in both simulation and real vehicles.[4] These results support the value of exploring challenging conditions and failure modes within constrained scenarios. Translating that value into better robot learning still requires real-robot validation.
We organize data collection around identified failures and boundaries, running repeatable tests near relevant poses, contacts, object properties, and perturbations while retaining success, failure, and recovery trajectories. We measure diversity by the failure mechanisms, boundary conditions, and recovery paths covered—not simply by the number of tasks or failure samples.
The same experience can improve several components: RimPilot learns actions and recovery; RimCritic refines its criteria and identifies early signs of failure; RimGround reconstructs difficult conditions. Problems that training alone cannot solve enter the embodiment improvement workflow. What matters is accumulating the full chain of boundary discovery—diagnosis—intervention—validation. Boundary tests support diagnosis, while representative task tests assess overall performance. Together, they establish whether an intervention helps.
RimCritic: learning how to evaluate from experience
Evaluation determines the direction of optimization. We want RimCritic to identify task success, progress, and recoverability, and gradually generalize to new objects and conditions. Modeling the consequences of actions and future states may help distinguish temporary stalls from unrecoverable failures. Whether a world model outperforms direct evaluation must be established through both evaluation quality and downstream policy benefits.
Here we present offline evaluation results for RimCritic-Preview-0915 and six comparison models. These experiments measure evaluation capability; they do not yet demonstrate real-robot training benefits or recursive improvement.
Metrics and aggregation
- VOC
- Rank correlation between predicted progress and temporal order, primarily used to assess progress ordering in expert trajectories.
- VROC
- Progress-ordering correlation for reversed inputs. The gap relative to VOC also helps interpret directional consistency.
- PRC
- Rank correlation between predicted progress and annotated progress.
- PRC-minus
- PRC for reversed inputs, using the definition confirmed for this evaluation.
- TSA
- Accuracy of success classification at the final trajectory state.
The charts also retain VOC_F1, PRC_F1, AP_PLUS, and AP_MINUS, using the names in the experimental statistics. Bridge + Fractal gives equal weight to the two subsets; VPB Unseen equally weights expert unseen and nonexpert unseen. In the full-set aggregate, VOC, VROC, and VOC_F1 cover 8 evaluation sets, while PRC, PRC_MINUS, and PRC_F1 cover the 6 sets where all are valid. Subsets are equally weighted.
The interpretations of VOC and VROC follow VLAC; PRC and TSA follow the public VPB evaluation documentation.[6][7] High VOC on nonexpert or failed trajectories does not directly imply more accurate failure recognition; reversed-input metrics are also needed. “Unseen” follows the benchmark's split labels and does not mean that overlap with each model's training data has been independently verified.
RimCritic-Preview-0915 · Offline evaluation
All radar charts use the same radial range: −0.5 to 1.0.
Bridge + Fractal
Equal-weight average of two subsets · 9 metrics
VPB Unseen
Equal-weight average of expert unseen and nonexpert unseen · OOD view
Full set
Equal-weight average across all valid evaluation sets for each metric
The dashed ring marks 0; the outer ring marks 1.0. Missing results for GVL + Google Gemini 3.8 Flash are plotted as 0, and its series uses long dashes. Zero imputation is for visualization only and does not indicate a measured score of 0. Click a legend item to show or hide a model; hover over a data point to inspect its value.
Within the models and metrics covered by this offline evaluation, RimCritic-Preview-0915 reaches state-of-the-art performance and exceeds the comparison models on some metrics. On VPB Unseen, for example, its VROC is 0.8838, above the highest comparison score of 0.6754. On the full set, its VROC is 0.8662, also above the highest comparison score of 0.7238. We will publish a formal RimCritic report with further analysis of robustness, efficiency, and performance across tasks and evaluation conditions.
Forward expert · Move the green can next to the Red Bull can
Predicted progress broadly follows the increasing annotation, reaching approximately 0.977 at the end. The video demonstrates future-frame generation for the same training-set example.
Reversed trajectory · Place the orange object on the purple towel
When the trajectory is reversed, both annotated and predicted progress fall from 1 to 0, demonstrating the model's ability to distinguish the direction of task progress.
RimCritic · Data scaling trends
Across these three experimental scales, VOC, VROC, and TSA on both VPB Expert Seen and Unseen improve as training data grows in volume and source coverage, showing an initial data scaling trend.
① Bridge: 753,507 frames
② Bridge + Fractal: 3,274,841 frames
③ Bridge + Fractal + BC-Z + Galaxea Open World: 7,694,161 frames
As the dataset grows from approximately 0.75 million to 7.69 million frames, Unseen VROC rises from 0.545 to 0.884, and TSA from 22.2% to 40.1%. We are particularly interested in accumulating failure and boundary data to improve judgments about early signs of failure, regressing progress, and recoverability.
The horizontal axis sums the sampled frames across training datasets; the vertical axis shows the original metric values. Hover over a point for exact values. Since PRC is close to VOC and PRC-minus is close to VROC, we follow the source document in showing three metrics. Both data volume and composition change in these experiments; the incremental contribution of failure data has not been isolated. These three scales show the trend observed so far.
Real outcomes must continue to correct evaluation—for example, using electrical continuity checks, force signals, or human verification to correct cases that only appear successful. As evaluators and policies are updated together, we will retain independent external outcome criteria and test sets to avoid higher model scores without real benefits. Next, we need to validate evaluation generalization, failure prediction, and real-robot benefits after integration with RimPilot under comparable budgets.
RimGround: simulation that addresses real weaknesses
Deployment experience determines training priorities. Starting from real-robot failures and boundary data, RimGround reconstructs relevant scenes and edits layouts, contact parameters, visual conditions, and perturbations to create curricula covering success, failure, and recovery near capability boundaries.
From a real workstation to continual learning in simulation
Starting with photographs of our real working environment at Huaqin Yuantu, the animation below illustrates the transition from the real world to a virtual simulation environment, followed by continual learning in simulation.
From real photographs to trainable simulation environments
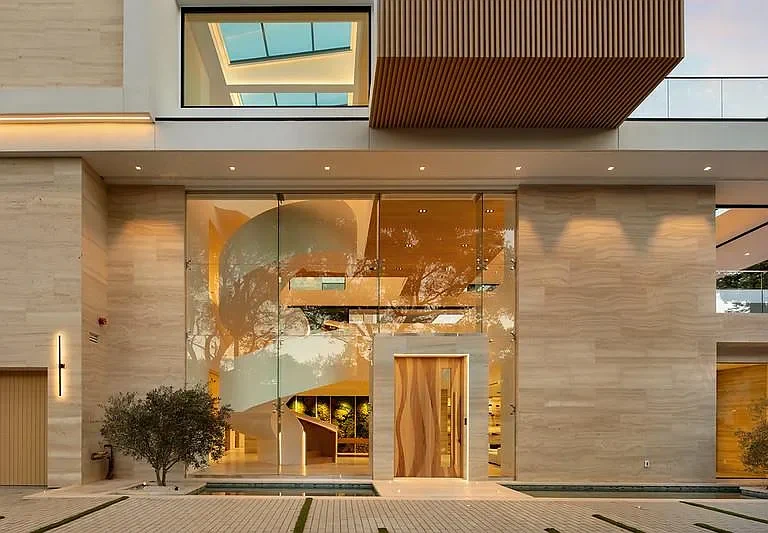
Reconstructing spaces from real photographs, generating 3D assets, and assembling editable scenes is becoming an increasingly mature technical approach. We are interested in its potential to transfer across objects, layouts, and work environments: using on-site material to shorten environment construction cycles so that simulation can keep up with new conditions in real deployments. The photographs and videos below illustrate this approach in several settings.
Photo-to-3D scene · Spatial reconstruction example
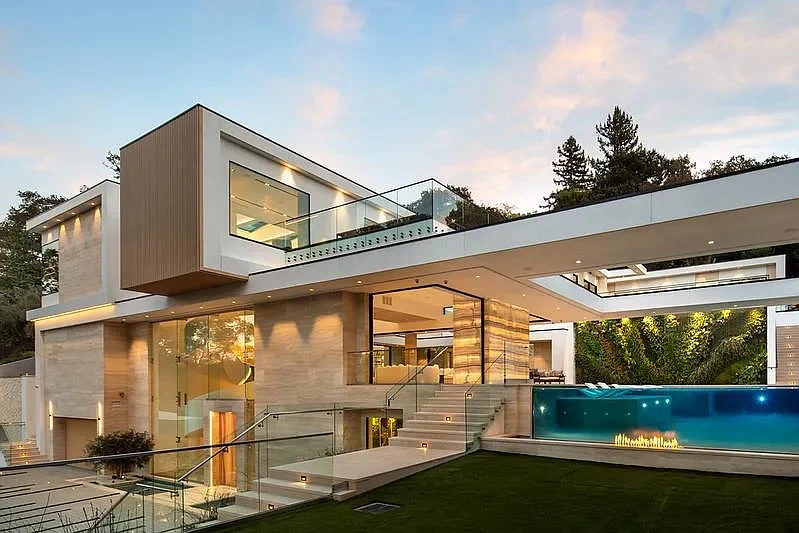
View another reference photo: building entrance
Play to explore the 3D space reconstructed from reference photographs.
Original reference-image post ↗ · Original model demonstration ↗ · Tripo case page ↗
These examples demonstrate the foundations of scene reconstruction. For robot learning, we will add physical interaction, task definitions, and real-robot calibration. The external video requires an internet connection.
RimGround: a scene generation workflow for continual learning
We will build on these increasingly mature reconstruction and generation methods to implement the workflow illustrated in the Huaqin Yuantu animation above. Real workstation photographs and deployment experience will become trainable, editable simulation environments; training will continually target failures and capability boundaries before returning to real robots for validation. This is the loop shown in Figure 03. For a connector-insertion workstation, for example, we will turn multi-view photographs of the workbench and fixtures, connector dimensions, and failure trajectories into scene inputs, organizing factors that affect success into controllable, reproducible environment variables.
- Reconstruct and calibrate: separate the workbench, fixtures, connectors, and obstacles, then align coordinate systems and measured dimensions. Occluded areas, contact surfaces, and socket geometry require additional photographs, measurements, or CAD constraints.
- Add physical interaction: configure collision geometry, mass, friction, joints, and contact parameters; integrate robot actions, observations, success criteria, and reset logic. Calibrate key parameters against real measurements.
- Edit curricula around failures: vary connector misalignment, fixture offsets, occlusion, lighting, and friction to create families of scenes covering success, jamming, and recovery, while retaining reproducible parameter records.
- Select by real-robot benefits: test whether new scenes improve success rates and recovery under comparable training budgets, and retain effective scene-editing methods for future tasks.
Reproducing failure mechanisms matters more than visual similarity. Scenes must reproduce the relevant difficulties under the key physical conditions to help solve deployment problems. The ultimate test of a curriculum is whether the generated environments improve real-world success, recovery, and robustness under the same training budget.
The recursive objective is to improve how curricula are selected. Learning which training interventions address which failures makes subsequent environment generation and editing more effective. In asynchronous RL combining simulation and real robots, RimGround improves noise diversity and efficiency in simulated environments. A small number of real-robot environments continually calibrate physical laws and parameters and validate actual outcomes. Environment generation alone cannot remove constraints from physical resets, wear, or experimental throughput.
From industrial skills to physical experiments and embodiment improvement
Industry is our first validation environment. We prioritize bounded, verifiable, repeatable settings such as cable handling and connector insertion and removal. We first make individual skills reliable and efficient, then test whether adaptation cycles keep shortening as objects, fixtures, and manufacturing operations change. High-quality atomic skills connect to higher-level task orchestration: customers receive usable robotic skills and systems, while Physical RSI supports continued delivery.
Laboratories are a second validation domain. We will explore whether evaluation, environment construction, and skill learning workflows transfer to physical experiments, rather than assuming that industrial experience generalizes automatically. Embodiment RSI is a parallel path. Using the super workstation jointly proposed with Yuantu, we will begin with bounded changes such as replaceable end effectors, testing whether physical improvements enhance both task performance and subsequent learning efficiency.
Under the same reliability requirements and comparable budgets, we will test whether this experience helps new tasks excluded from optimization reach requirements faster, and whether multiple rounds keep reducing adaptation time, interaction costs, and human effort. We will also measure task complexity through concrete dimensions such as contact precision, operational steps, and recovery requirements to establish whether the capability range has expanded. Improvements in offline evaluation must ultimately translate into repeatable real-robot benefits.
Every deployment should leave reusable experience
that helps acquire the next capability.
The long-term value of Physical RSI will be measured by whether robots learn new skills faster and master increasingly complex skills—and whether this translates into shorter adaptation cycles for new industrial operations.
References
- Generalist — Towards Machines with a Thousand Hands ↗
2026 · Training across end effectors and model adaptation.
- General Robotics — Introducing Auto Engineering for Robotics ↗
2026 · An automated engineering loop; its definition of Auto Engineering is broader than the embodiment path discussed here.
- The Ingredients of Real-World Robotic Reinforcement Learning ↗
2020 · Reward, perception, and reset challenges in autonomous real-robot learning.
- The Implementation of Safety Acceptance Evaluation for Highly Automated Vehicles ↗
X. Wang, T. Wang, S. Xu, Y. Zhong, H. Peng. 2023 · International Journal of Automotive Engineering, 14(3), 58–65.
- Comprehensive Safety Evaluation of Highly Automated Vehicles at the Roundabout Scenario ↗
X. Wang, S. Zhang, H. Peng. 2022 · IEEE T-ITS, 23(11), 20873–20888.
- VLAC: A Vision-Language-Action-Critic Model for Robotic Real-World Reinforcement Learning ↗
2025 · Definitions and interpretation of VOC and VROC.
- VLAC-Cut — Evaluating on Video Progress Benchmark ↗
Public evaluation documentation · PRC, VOC, and final-state success evaluation. The specific implementation of this internal evaluation requires independent confirmation.